Uptime Is a Cultural Artefact, Not Just an Engineering Metric
Trace most major outages back far enough and you rarely land on a technical failure — you land on a handoff, an incentive, or a structure that quietly made the failure possible.
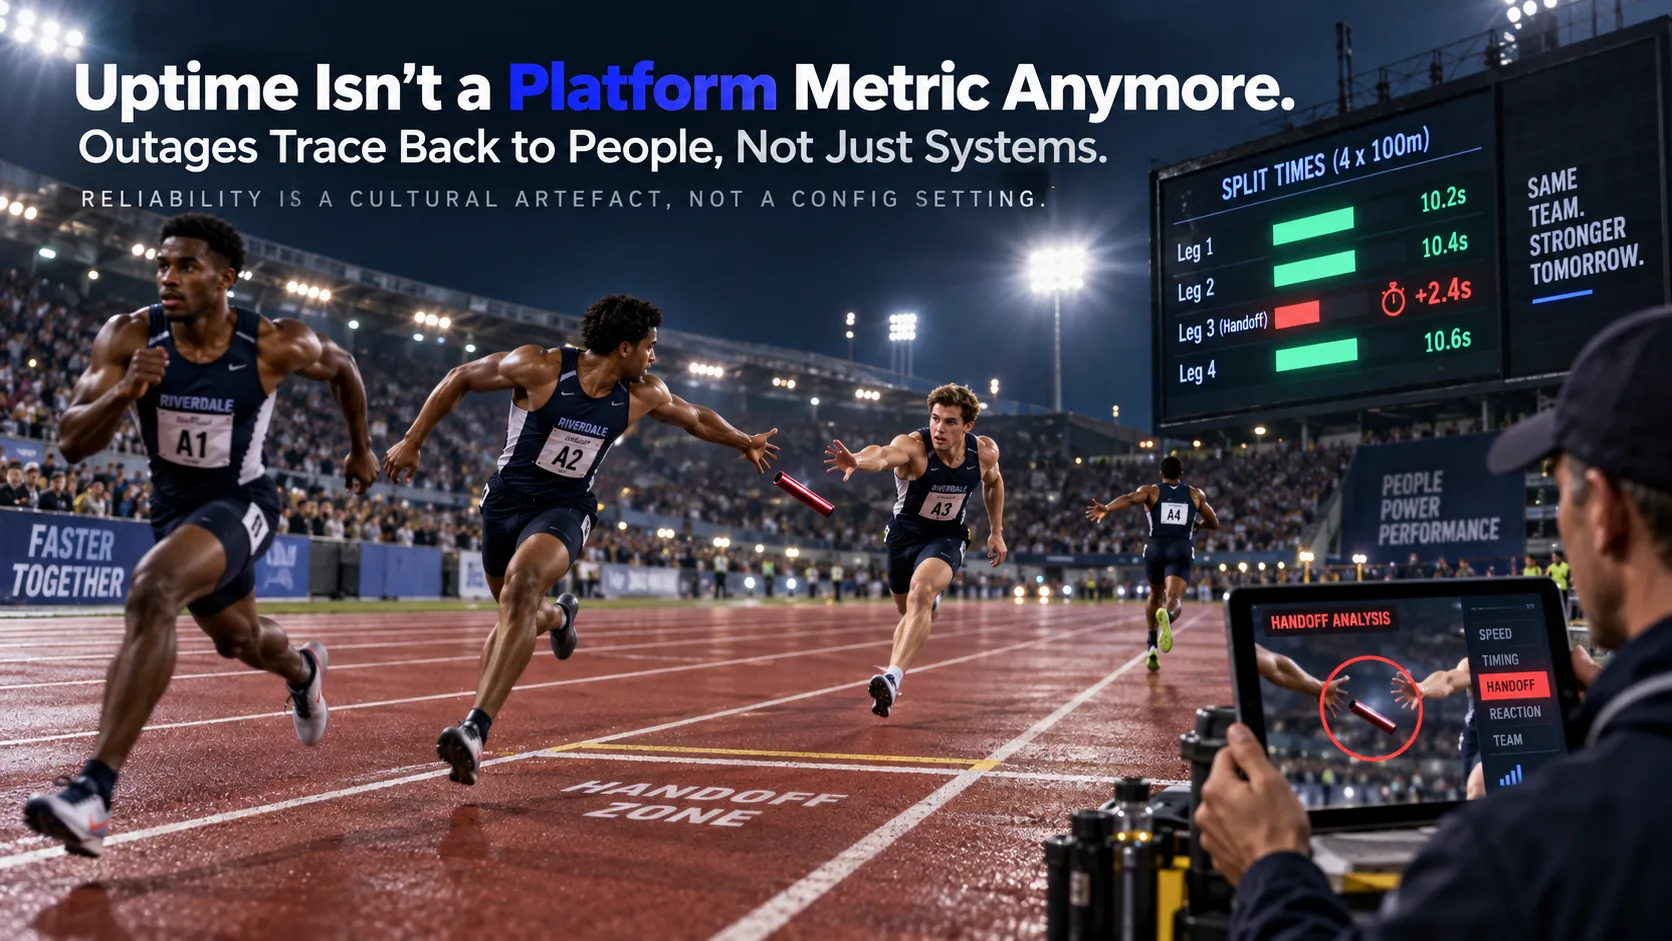
Reliability engineering has matured considerably: redundancy is standard, observability tooling is mature, chaos testing is common practice at scale. And yet significant outages keep happening, often at organisations that have invested seriously in all three. The remaining failure mode is less often technical than it looks on the incident timeline.
Where outages actually start
Pull apart most post-incident reviews and the root cause is rarely a single missing technical control. It’s a handoff: an on-call transition where context didn’t transfer cleanly, a dependency between two teams where ownership was assumed rather than confirmed, a 2am judgement call made by someone without the authority — or the confidence — to escalate it.
Incentives quietly shape reliability
Teams rewarded primarily for shipping velocity, with no equivalent recognition for the invisible work of preventing incidents that never happen, will structurally under-invest in reliability — regardless of how good the tooling available to them is. Nobody gets promoted for the outage that didn’t occur.
A structural audit, not just a technical one
- Who owns a problem that spans two teams’ boundaries, and is that ownership written down anywhere?
- Does anyone get credit — in review, in comp, in visibility — for the incident that didn’t happen?
- What happens, culturally, to the engineer who escalates "too early" and is wrong?
Reliability as a property, not a project
The platform work — redundancy, monitoring, testing — remains necessary. It has simply stopped being sufficient on its own. The organisations with the fewest surprising outages tend to be the ones that treat reliability as a property of how ownership and incentives are structured, not a checklist to complete once and consider finished.
Ready to put these insights into practice?
Let's discuss how we can help you achieve similar results